Small Models, Structured Data: Can Lightweight VLMs Replace Cloud APIs for Complex Document Extraction?
By Gregory Hain
Based on: From Pixels to Structure: Lightweight Vision-Language Models for Document OCR and Structured JSON Extraction — Uddipan Basu Bir, Vincent Christlein, Andreas Maier, Mathias Zinnen
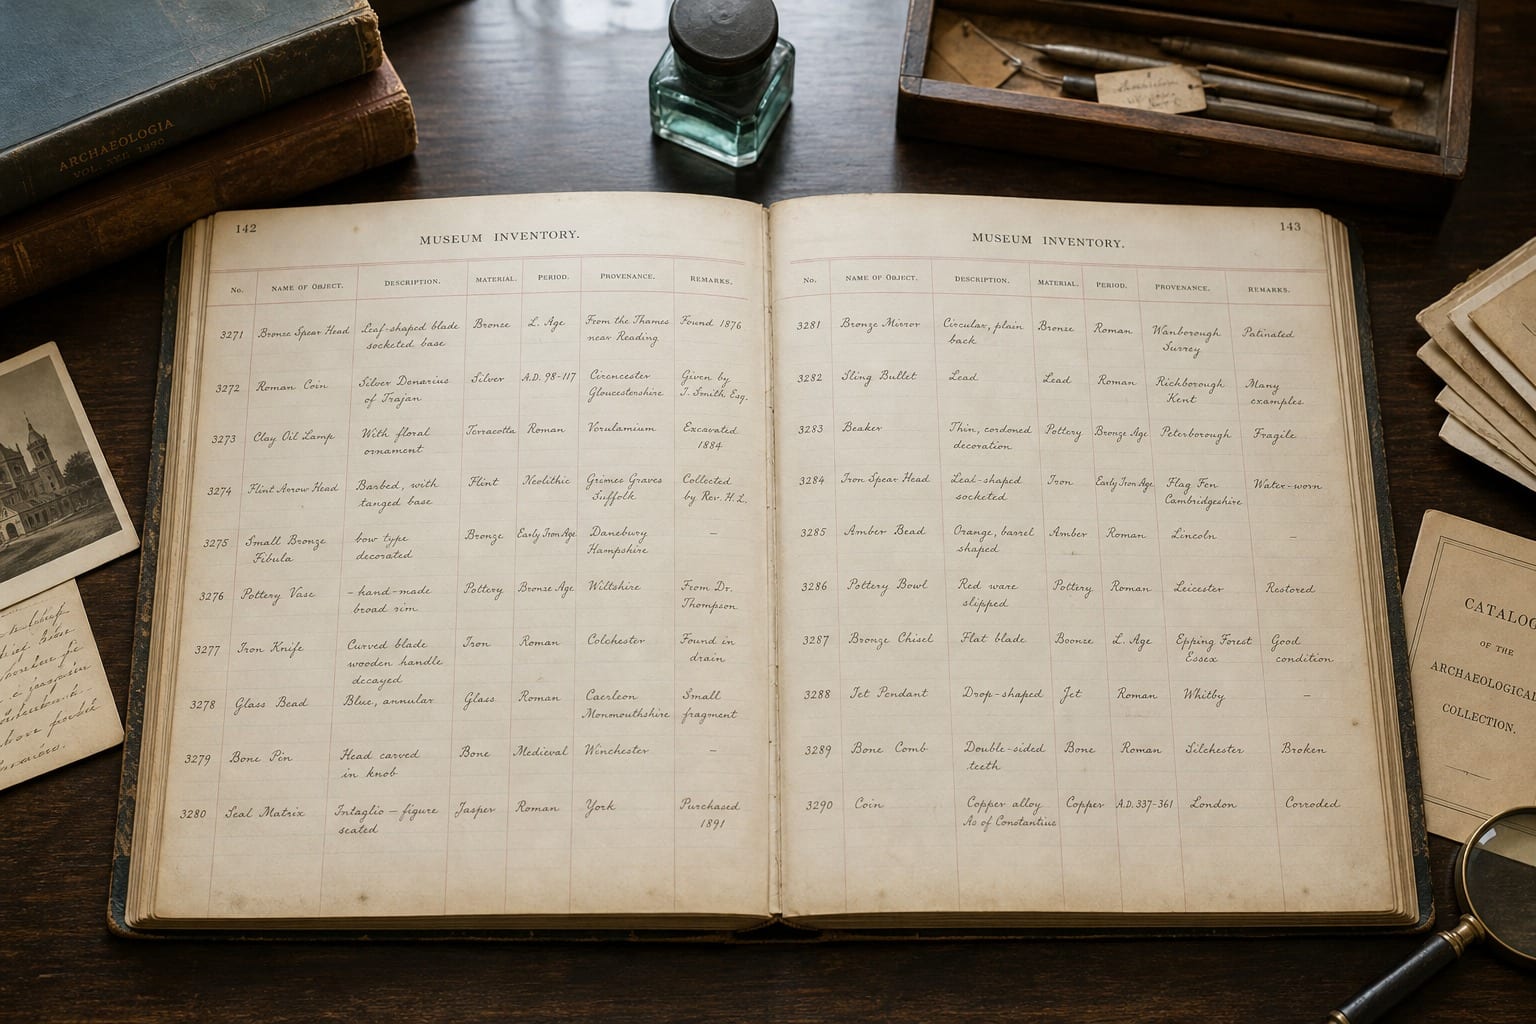
Hand a clean digital invoice to a multimodal model, and extracting key-value pairs may look straightforward. But try handing that same model a historical German archaeological register written in cursive script, or an architectural survey mixing printed labels, handwritten entries, and technical checkboxes. Reading the words is only part of the job.
Traditional approaches combine multiple stages: image binarization, layout segmentation, external Optical Character Recognition (OCR) engines like Tesseract, and downstream Key Information Extraction (KIE) models like LayoutLM. Large commercial Vision-Language Models (VLMs) offer another route, but bring their own deployment constraints.
For institutions in the GLAM sector (Galleries, Libraries, Archives, and Museums), cloud APIs can present substantial barriers. Sending archival records to commercial providers raises data autonomy concerns, introduces recurring costs, and prompts questions about the environmental footprint of large-scale computation. These concerns motivate local alternatives; they are not cost or energy measurements from this study.
A research team from Friedrich-Alexander-Universität Erlangen-Nürnberg (FAU) addressed this bottleneck in their paper, From Pixels to Structure: Lightweight Vision-Language Models for Document OCR and Structured JSON Extraction (Uddipan Basu Bir, Vincent Christlein, Andreas Maier, and Mathias Zinnen, October 8, 2026, arXiv:2610.11818). The authors asked a direct engineering question: can lightweight VLMs with 7 billion parameters or fewer transcribe historical documents and generate schema-guided JSON suitable for institution-controlled processing?
The researchers evaluated eight models across three specialized German archival collections. Along the way, they uncovered practical insights that complicate conventional document-processing advice, especially regarding prompt demonstrations, classical image filters, and training one checkpoint across multiple collections.
Three Collections, Three Nightmares: Cursive, Catalog Cards, and Nested Stairs
Evaluating structured document extraction requires testing models against realistic archival challenges. The authors assembled a 1,062-document benchmark across three distinct collections, using approximately 70% training, 15% validation, and 15% test splits:
+------------------------+-------+-------+-----+------+-------------------+--------------------------------+
| Dataset                | Total | Train | Val | Test | Text Type         | Schema Complexity              |
+------------------------+-------+-------+-----+------+-------------------+--------------------------------+
| Erlangen-Prehistoric    |   308 |   216 |  46 |   46 | Handwritten       | Medium (8 top-level fields)    |
| Pforzheim Jewelry       |   590 |   413 |  88 |   89 | Mostly printed    | Medium (17 flat fields)        |
| Regensburg Scalalogy    |   164 |   114 |  25 |   25 | Mixed (print/pen) | High (deeply nested, booleans)  |
| Total                  | 1,062 |   743 | 159 |  160 | —                 | —                              |
+------------------------+-------+-------+-----+------+-------------------+--------------------------------+
Each collection represents a distinct structural hurdle:
- Erlangen-Prehistoric Dataset: Originating from FAU's Inventarbuch der Anthropologisch Prähistorischen Sammlung, these 308 pages feature historical handwriting alongside printed headers or labels. The illustrated target JSON schema contains eight top-level fields, including an image identifier and artifact dimensions (
Maße) nested intoL,B, andD. Other fields include discovery location (Fundort), find date (Fundzeit), and descriptive notes (Beschreibungstext). Ground-truth transcriptions were generated using Gemini and manually verified before publication on Zenodo. - Pforzheim Jewelry Dataset: Sourced from the KUPFER research project at HS Pforzheim, this collection contains 590 historical inventory cards describing jewelry acquired between 1879 and 1970. The cards were derived from historical books when the objects moved on permanent loan to the Pforzheim Jewellery Museum around 1980. The documents are mostly printed but demand extraction across a dense 17-field schema covering material, weight, purchase price, and insurance value (
Vers.-Wert). - Regensburg Scalalogy Dataset: The structural stress test. Sourced from the Friedrich Mielke Institute for Scalalogy (FMIS) at OTH Regensburg, these 164 survey forms document staircase architecture using specialized terminology. The target JSON schema is deeply nested, featuring boolean flags for structural traits, including inner and outer housing categories (
GEHÄUSE), rotation direction (LAUF), and handrail placement (HANDLAUF), alongside integer measurements and stair-step counts (STUFEN).
If an archival field was illegible or absent, the task required text fields to be empty strings ("") and boolean fields to be false. Each collection had a fixed target schema, so success required placing extracted content into the appropriate fields as well as recognizing it.
The 8-Model Showdown and the Prompting Divide
The authors evaluated eight models, described in the paper as open-source VLMs, ranging from 200M to 7B parameters:
- Donut-Base (200M) and Donut-CORD (200M): OCR-free encoder-decoder models.
- Florence-2-Large (0.77B): A unified vision-language model.
- PaddleOCR-VL (0.9B): An OCR-specialized vision-language model.
- Nanonets-OCR-s (4B): An OCR-specialized VLM.
- Gemma-3-4B (4B): An instruction-tuned VLM.
- Phi-3.5-Vision (4.2B): An instruction-tuned VLM.
- Qwen2.5-VL-7B (7B): An instruction-tuned VLM.
A crucial contribution of this study is its constraint-aware evaluation protocol. Benchmarking diverse VLMs is tricky because their supported interfaces differ.
Under the study's protocol, Donut, Florence-2-Large, and PaddleOCR-VL used fixed OCR-style prompts or task-specific tokens, such as <OCR> or <s_cord-v2>. They were not given arbitrary conversational instructions or few-shot demonstrations. The authors applied minimal post-processing—removing wrappers, chat prefixes, whitespace, and code fences—before attempting JSON parsing.
By contrast, Gemma-3-4B, Phi-3.5-Vision, Qwen2.5-VL-7B, and Nanonets-OCR-s were evaluated with custom natural-language prompts. In zero-shot evaluation, those prompts included the target JSON skeleton and requested output following that schema.
This distinction matters when interpreting the results: the benchmark measures OCR-to-JSON performance through the interfaces used in the study, rather than giving every model an identical schema-bearing prompt.
Why Standard OCR Metrics Can Miss Structured JSON Failures
Evaluating structured document AI requires measuring both output fidelity and structural reliability. Recognizable text can still be unusable for direct ingestion if the model returns malformed JSON or assigns values to the wrong fields.
The authors tracked three complementary metrics:
- Character Error Rate (CER): Measures character-level edit errors relative to the canonical ground-truth JSON string, normalized by reference length; lower is better. Parsed predictions are serialized into the same canonical format before comparison. If parsing fails, the raw output is compared against the canonical reference. This measures fidelity of the JSON text, including structure, rather than transcription accuracy alone.
- Approximate Normalized Levenshtein Similarity (ANLS*): A structured similarity metric using a threshold of $\tau = 0.5$, with similarities below that threshold set to zero. If output parses as JSON, it evaluates the nested objects; if parsing fails, it falls back to string-level similarity against the canonical ground-truth JSON string.
- Mean Average Precision F1 (mAP-F1): The study's structure-first metric. Inspired by object-detection evaluation protocols and DAN's mAPCER, it flattens predictions and ground truth into dot-notated leaf keys, such as
GEHÄUSE.innen.1. Per-field overlap scores ($1 - \text{CER}$) are evaluated at four thresholds: $\theta \in {0.3, 0.5, 0.7, 0.8}$. Precision and recall are macro-averaged across fields to compute an F1 score at each threshold, and mAP-F1 is the mean across all four.
Crucially, if the output does not parse into a Python dictionary through json.loads, mAP-F1 is scored as 0.0%. CER and ANLS* can still award partial credit through their raw-text comparisons.
The authors also tracked JSON validity separately. Gemma-3, Phi-3.5-Vision, and Qwen2.5-VL maintained approximately 95%–100% validity across datasets and settings, although the main tables omit those rates. Parsing successfully does not, by itself, establish that every field or value is correct.
Meanwhile, Donut, Florence-2, and PaddleOCR-VL had much lower JSON validity. All scored 0.0% mAP-F1 in zero-shot evaluation, even where CER or ANLS* showed that their outputs retained some reference content.
Zero-Shot, Few-Shot, and the In-Context Prompting Trap
In the zero-shot setting, prompt-flexible models led the structured-extraction results. Qwen2.5-VL-7B achieved the highest ANLS* and mAP-F1 on all three datasets. On Pforzheim Jewelry, it reached 2.6% CER, 96.0% ANLS*, and 96.3% mAP-F1, although Nanonets-OCR-s had lower CER at 1.9%. On handwritten Erlangen-Prehistoric records, Qwen reached 21.4% CER and 56.2% mAP-F1.
All metric values in the result tables below are percentages.
+------------------+--------------------------+--------------------------+--------------------------+
|                  |   Erlangen-Prehistoric   |     Pforzheim Jewelry    |   Regensburg Scalalogy   |
| Zero-Shot Model  |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |
+------------------+--------------------------+--------------------------+--------------------------+
| Donut-Base       |  93.4      0.0      0.0  |  97.2      0.0      0.0  |  90.1      0.0      0.0  |
| Donut-CORD       |  78.8      0.0      0.0  |  91.9      0.0      0.0  |  93.1      0.0      0.0  |
| Florence-2-Large |  45.6     50.4      0.0  |  33.6     66.4      0.0  |  75.6      0.0      0.0  |
| Nanonets-OCR-s   |  25.7     49.4     28.5  |   1.9     86.5     86.5  |  39.3     22.8     15.2  |
| PaddleOCR-VL     |  69.2     20.1      0.0  |  51.3     57.0      0.0  |  78.1      0.0      0.0  |
| Gemma-3-4B       |  33.6     41.8     34.6  |   4.4     92.1     87.4  |  37.6     26.3     22.5  |
| Phi-3.5-Vision   |  50.9     28.1     23.4  |   7.3     85.3     67.9  |  28.7     57.1     27.9  |
| Qwen2.5-VL-7B    |  21.4     54.0     56.2  |   2.6     96.0     96.3  |  21.3     67.0     33.3  |
+------------------+--------------------------+--------------------------+--------------------------+
When the authors tested few-shot in-context learning, they supplied image–JSON demonstrations sampled from the training set: one for Pforzheim Jewelry and two for Erlangen-Prehistoric and Regensburg Scalalogy. Only the four prompt-flexible models participated.
The result was a useful warning: few-shot prompting did not consistently improve complex-document extraction.
+------------------+--------------------------+--------------------------+--------------------------+
| Few-Shot Model   |   Erlangen-Prehistoric   |     Pforzheim Jewelry    |   Regensburg Scalalogy   |
| (1-2 Examples)   |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |
+------------------+--------------------------+--------------------------+--------------------------+
| Nanonets-OCR-s   |  61.9     53.3     44.7  |   1.7     93.1     90.7  |  33.3     44.5     44.9  |
| Gemma-3-4B       |  26.8     61.7     53.6  |   2.0     97.3     92.1  |  34.9     33.8     20.2  |
| Phi-3.5-Vision   |  59.3     40.7     38.9  |   7.2     85.9     71.1  |  52.7     27.5     23.1  |
| Qwen2.5-VL-7B    |  18.9     79.0     74.7  |   0.9     98.9     99.4  |  24.1     55.6     30.7  |
+------------------+--------------------------+--------------------------+--------------------------+
Few-shot prompting helped all four models on Pforzheim Jewelry across the reported metrics. Qwen2.5-VL's CER dropped from 2.6% to 0.9%, while mAP-F1 rose to 99.4%. Elsewhere, the picture was mixed:
- Nanonets-OCR-s saw its CER on Erlangen-Prehistoric handwriting rise from 25.7% to 61.9%, even as ANLS* and mAP-F1 improved.
- Gemma-3-4B's mAP-F1 on Regensburg Scalalogy dropped from 22.5% to 20.2%, despite improvements in CER and ANLS*.
- Phi-3.5-Vision's CER on Scalalogy worsened from 28.7% to 52.7%, alongside declines in the other two metrics.
- Qwen and Gemma improved across all three metrics on Erlangen-Prehistoric, while Nanonets improved across all three on Scalalogy.
Why did demonstrations help some settings and hurt others? The authors suggest that longer prompts can increase instruction complexity, but the experiments do not establish a specific attention or visual-encoding mechanism. The supported lesson is narrower: examples are an adaptation strategy to test, not a guaranteed upgrade.
Local Fine-Tuning: QLoRA on a 32GB GPU
The authors also fine-tuned every evaluated model.
For models under 1B parameters, they performed full-parameter fine-tuning. For the larger models, they used Quantized Low-Rank Adaptation (QLoRA), combining 4-bit quantization with LoRA adapters in the attention and MLP layers while keeping base weights frozen. The methods section specifies an NVIDIA V100 with 32GB VRAM for this QLoRA setup.
Checkpoint selection used the lowest autoregressive validation CER, and test evaluation used autoregressive generation. This is image-to-JSON generation, not a single forward pass producing an entire document's output at once.
+------------------+--------------------------+--------------------------+--------------------------+
| Fine-Tuning      |   Erlangen-Prehistoric   |     Pforzheim Jewelry    |   Regensburg Scalalogy   |
| Baseline Results |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |
+------------------+--------------------------+--------------------------+--------------------------+
| Donut-Base       |  16.4     78.0      0.0  |   6.3     93.6      0.0  |  59.5      0.0      0.0  |
| Donut-CORD       |  20.6     75.0      0.0  |   6.9     92.9      0.0  |  66.0      0.0      0.0  |
| Florence-2-Large |  10.7     75.5     45.4  |  11.1     89.9      0.0  |  57.4      4.3      0.0  |
| Nanonets-OCR-s   |  23.0     82.5     81.2  |   0.5     96.7     87.2  |  20.2     79.9     50.7  |
| PaddleOCR-VL     |  13.7     90.1     85.3  |   1.1     98.7     84.7  |  65.1      0.0      0.0  |
| Gemma-3-4B       |  10.4     88.6     83.1  |   0.9     99.0     99.4  |  14.6     73.8     46.9  |
| Phi-3.5-Vision   |  17.9     86.5     82.2  |   0.3     99.4     99.5  |   6.3     90.1     72.0  |
| Qwen2.5-VL-7B    |   5.8     91.0     90.0  |   0.5     99.2     99.4  |   7.6     87.0     62.8  |
+------------------+--------------------------+--------------------------+--------------------------+
Fine-tuning delivered substantial gains over zero-shot evaluation for the strongest structured-extraction models:
- Qwen2.5-VL-7B reached 5.8% CER and 90.0% mAP-F1 on handwritten Erlangen-Prehistoric records.
- Phi-3.5-Vision led the baseline fine-tuning results on Regensburg Scalalogy, reaching 6.3% CER, 90.1% ANLS*, and 72.0% mAP-F1, up from 27.9% mAP-F1 in zero-shot evaluation.
- Gemma-3-4B reached 99.4% mAP-F1 on jewelry and 83.1% on prehistoric records, although its 46.9% mAP-F1 on Scalalogy showed that nested extraction remained difficult.
Fine-tuning did not resolve every structural failure. Both Donut variants still scored 0.0% mAP-F1 across the three datasets. Conversely, PaddleOCR-VL reached 85.3% mAP-F1 on Erlangen-Prehistoric, demonstrating that the OCR-specialized models were not uniformly unsuccessful.
Based on performance across zero-shot, few-shot, and fine-tuning settings, alongside stable JSON generation, the authors selected Gemma-3-4B, Phi-3.5-Vision, and Qwen2.5-VL-7B for three secondary studies.
Testing Document AI Folk Wisdom: Preprocessing and HPO Are Not Automatic Wins
The authors tested hyperparameter optimization, image preprocessing, and multi-stage training against the standard fine-tuning baseline. Each intervention was evaluated independently, so these results do not describe a pipeline combining all three.
Study 1: Hyperparameter Optimization (HPO)
Using Optuna with a Tree-structured Parzen Estimator (TPE) sampler, the authors ran 20 trials of 5 epochs each, optimizing validation CER. They then used the selected hyperparameters in a full training run through the baseline fine-tuning code. The paper does not specify the search space or selected parameter values.
+-------------------------+--------------------------+--------------------------+--------------------------+
| Hyperparameter Tuning   |   Erlangen-Prehistoric   |     Pforzheim Jewelry    |   Regensburg Scalalogy   |
| (Optuna vs Default)     |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |
+-------------------------+--------------------------+--------------------------+--------------------------+
| Gemma-3-4B (Default)    |  10.4     88.6     83.1  |   0.9     99.0     99.4  |  14.6     73.8     46.9  |
| Gemma-3-4B (HPO)        |   9.3     88.8     65.4  |   0.4     99.2     99.5  |   3.4     92.3     77.9  |
| Phi-3.5-Vision (Default)|  17.9     86.5     82.2  |   0.3     99.4     99.5  |   6.3     90.1     72.0  |
| Phi-3.5-Vision (HPO)    |  17.7     84.0     81.2  |   0.3     99.5     99.7  |   3.2     91.8     73.8  |
| Qwen2.5-VL-7B (Default) |   5.8     91.0     90.0  |   0.5     99.2     99.4  |   7.6     87.0     62.8  |
| Qwen2.5-VL-7B (HPO)     |   4.3     93.4     91.2  |   0.5     99.3     99.5  |   3.1     89.4     67.1  |
+-------------------------+--------------------------+--------------------------+--------------------------+
The findings were striking:
- On Regensburg Scalalogy, HPO improved all three metrics for all three models. Gemma-3-4B's CER dropped from 14.6% to 3.4%, while its mAP-F1 rose from 46.9% to 77.9%. Qwen2.5-VL's CER dropped from 7.6% to 3.1%, and Phi's from 6.3% to 3.2%.
- On Pforzheim Jewelry, absolute improvements were comparatively small because baseline scores were already strong.
- On Erlangen-Prehistoric, HPO helped Qwen across all three metrics. Gemma's CER improved from 10.4% to 9.3%, but mAP-F1 fell from 83.1% to 65.4%. Phi's CER improved slightly while ANLS* and mAP-F1 declined.
That divergence matters: selecting hyperparameters by validation CER did not guarantee better test-set structured extraction. The results demonstrate a mismatch between metric outcomes, without identifying exactly which field errors caused it.
Study 2: The Image Preprocessing Trap
The authors constructed a four-step classical preprocessing pipeline:
- Illumination Flattening: Grayscale conversion, morphological opening to estimate background illumination, and normalization to reduce uneven lighting.
- Denoising: Bilateral filtering by default, or Non-Local Means denoising, to reduce noise while preserving edges.
- Contrast Limited Adaptive Histogram Equalization (CLAHE): Enhancing local contrast on the luminance channel.
- Letterbox Resizing: Resizing to a fixed canvas with padding to preserve aspect ratio; the methods give $1024 \times 1024$ as an example.
They evaluated the complete pipeline on top of baseline fine-tuning against a raw-image baseline. “Raw” here means without this additional cleanup pipeline; images still underwent model-specific preprocessing.
+-------------------------+--------------------------+--------------------------+--------------------------+
| Image Preprocessing     |   Erlangen-Prehistoric   |     Pforzheim Jewelry    |   Regensburg Scalalogy   |
| (Raw vs Preprocessed)   |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |
+-------------------------+--------------------------+--------------------------+--------------------------+
| Gemma-3-4B (Raw)        |  10.4     88.6     83.1  |   0.9     99.0     99.4  |  14.6     73.8     46.9  |
| Gemma-3-4B (Preproc ✓)  |  10.4     88.8     85.3  |   1.2     97.6     97.7  |  16.4     69.7     43.6  |
| Phi-3.5-Vision (Raw)    |  17.9     86.5     82.2  |   0.3     99.4     99.5  |   6.3     90.1     72.0  |
| Phi-3.5-Vision (Pre ✓)  |  19.0     80.4     76.5  |   0.3     99.2     99.3  |   5.5     89.5     61.1  |
| Qwen2.5-VL-7B (Raw)     |   5.8     91.0     90.0  |   0.5     99.2     99.4  |   7.6     87.0     62.8  |
| Qwen2.5-VL-7B (Pre ✓)   |   5.2     90.0     87.4  |   0.7     99.1     99.3  |  12.0     81.7     53.6  |
+-------------------------+--------------------------+--------------------------+--------------------------+
The tested preprocessing pipeline reduced mAP-F1 in eight of the nine model–dataset combinations, although some other metrics improved.
On Regensburg Scalalogy:
- Qwen2.5-VL's CER worsened from 7.6% to 12.0%, and its mAP-F1 dropped from 62.8% to 53.6%.
- Phi-3.5-Vision's CER improved from 6.3% to 5.5%, but mAP-F1 fell from 72.0% to 61.1%.
- Gemma-3-4B's CER worsened from 14.6% to 16.4%, with declines in ANLS* and mAP-F1 as well.
There were exceptions elsewhere. Gemma's Erlangen-Prehistoric mAP-F1 rose from 83.1% to 85.3%, while Qwen's CER on the same dataset improved from 5.8% to 5.2% despite lower structured scores.
The experiment tested the full pipeline, not each filter independently. It therefore cannot identify whether denoising, contrast adjustment, illumination correction, resizing, or their combination caused a particular change. It also does not establish a neural mechanism for the regressions. The practical lesson is to compare preprocessing against a raw-image baseline using both fidelity and structured-extraction metrics.
Study 3: Multi-Stage Curriculum Training
The authors tested a two-stage schedule: a short warm-up using teacher forcing on supervised JSON targets at $3\times$ the base learning rate, followed by refinement on the same dataset at the base learning rate.
Validation ran each epoch, with checkpoint selection by lowest validation CER and early stopping after a patience period without improvement. The comparison used a single-stage baseline with the same total epoch budget and cosine learning-rate decay.
+-------------------------+--------------------------+--------------------------+--------------------------+
| Multi-Stage Training    |   Erlangen-Prehistoric   |     Pforzheim Jewelry    |   Regensburg Scalalogy   |
| (Single vs Multi-Stage) |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |
+-------------------------+--------------------------+--------------------------+--------------------------+
| Gemma-3-4B (Single)     |  10.4     88.6     83.1  |   0.9     99.0     99.4  |  14.6     73.8     46.9  |
| Gemma-3-4B (Multi-stage)|   8.1     89.9     86.5  |   0.4     99.3     99.5  |  10.3     80.2     63.8  |
| Phi-3.5-Vision (Single) |  17.9     86.5     82.2  |   0.3     99.4     99.5  |   6.3     90.1     72.0  |
| Phi-3.5-Vision (Multi)  |  18.0     86.7     83.0  |   0.3     99.5     99.7  |   4.9     90.5     72.5  |
| Qwen2.5-VL-7B (Single) |   5.8     91.0     90.0  |   0.5     99.2     99.4  |   7.6     87.0     62.8  |
| Qwen2.5-VL-7B (Multi)  |   5.8     91.4     89.1  |   0.7     88.5     90.2  |   7.8     86.0     57.8  |
+-------------------------+--------------------------+--------------------------+--------------------------+
Multi-stage training produced model-dependent results. It benefited Gemma-3-4B across all three metrics and collections, dropping prehistoric CER from 10.4% to 8.1% and raising Scalalogy mAP-F1 from 46.9% to 63.8%.
Phi improved across all three metrics on Scalalogy, with smaller or mixed changes elsewhere. Qwen showed only a slight ANLS* improvement on Erlangen-Prehistoric, with unchanged CER and lower mAP-F1. Its results worsened across all three metrics on both Jewelry and Scalalogy. The study establishes these outcome differences, without demonstrating that training instability caused them.
The Multi-Dataset Dilemma: Gemma's Gains, Qwen's Negative Transfer
In production, engineering teams may want a single checkpoint instead of separate models for every document collection. The authors tested this by fine-tuning each selected model once on the combined training sets of all three collections—743 documents total—using the standard fine-tuning recipe.
They then evaluated that checkpoint on each collection's test set and compared it with the corresponding dataset-specific checkpoint:
+-------------------------+--------------------------+--------------------------+--------------------------+
| Single-Dataset vs       |   Erlangen-Prehistoric   |     Pforzheim Jewelry    |   Regensburg Scalalogy   |
| Multi-Dataset Checkpoint|  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |  CER↓   ANLS*↑   mAP-F1↑ |
+-------------------------+--------------------------+--------------------------+--------------------------+
| Gemma-3-4B (Single)     |  10.4     88.6     83.1  |   0.9     99.0     99.4  |  14.6     73.8     46.9  |
| Gemma-3-4B (Multi-Joint)|   8.7     90.6     87.9  |   0.3     99.4     99.7  |   9.1     81.5     68.0  |
| Phi-3.5-Vision (Single) |  17.9     86.5     82.2  |   0.3     99.4     99.5  |   6.3     90.1     72.0  |
| Phi-3.5-Vision (Multi)  |  19.7     84.0     45.4  |   0.5     99.2     99.4  |   7.4     84.3     54.1  |
| Qwen2.5-VL-7B (Single)  |   5.8     91.0     90.0  |   0.5     99.2     99.4  |   7.6     87.0     62.8  |
| Qwen2.5-VL-7B (Multi)   |   7.1     89.3     91.9  |   1.6     98.2     99.1  |  24.9     65.2     41.4  |
+-------------------------+--------------------------+--------------------------+--------------------------+
This experiment revealed sharply different behavior across the three models:
- Gemma-3-4B benefited consistently from joint training. Its multi-dataset checkpoint outperformed the dataset-specific checkpoints across every reported metric. On Regensburg Scalalogy, CER dropped from 14.6% to 9.1% and mAP-F1 rose from 46.9% to 68.0%. These results support joint training for Gemma in this benchmark, without establishing how it would perform on an unseen collection.
- Qwen2.5-VL-7B showed substantial negative transfer on Scalalogy. CER rose from 7.6% to 24.9%, and mAP-F1 fell from 62.8% to 41.4%. CER and ANLS* worsened across all three collections, although Erlangen-Prehistoric mAP-F1 improved from 90.0% to 91.9%.
- Phi-3.5-Vision also declined across all three collections, with particularly large structured-extraction losses: prehistoric mAP-F1 fell from 82.2% to 45.4%, and Scalalogy mAP-F1 from 72.0% to 54.1%. Changes on Jewelry were much smaller.
The authors interpret the declines as signs of negative transfer across collections with different schemas and text modalities. The study does not isolate gradient interference, conflicting layouts, or any other specific cause. Deployment decisions therefore need per-collection evaluation: joint training helped one model throughout this benchmark and harmed others in important settings.
Where Models Still Struggle: Qualitative Failure Modes
Examining sample outputs highlights both the improvements fine-tuning can deliver and the errors that remain.
In Figure 4, the authors compare Gemma-3-4B's zero-shot and fine-tuned predictions for a handwritten Erlangen-Prehistoric page. The following abbreviated excerpts reproduce that comparison; the ellipses and bracketed notes are illustrative rather than complete model outputs.
Zero-shot prediction, sample CER: 26.8%.
{
  "Überschrift": "Anthropologisch-prähistorifche ...",
  "Inventarnummer": "J.-Nr. E024",
  "Maße": {"L": "", "B": "", "D": ""},
  "Objektbezeichnung": "Primitiver Kratzer",
  "Fundort": "Spay, Belgien",
  "Fundzeit": "Aumente Helin",
  "Beschreibungstext": "Flacher Stein ... [many OCR errors]"
}
Fine-tuned prediction, sample CER: 13.9%.
{
  "Überschrift": "Anthropologisch=prähistorische ...",
  "Inventarnummer": "Eo 24",
  "Maße": {"L": "6,25", "B": "3,95", "D": "1,7"},
  "Objektbezeichnung": "Primitiver Kratzer ...",
  "Fundort": "Spy, Belgien Ausbeute Helin",
  "Fundzeit": "",
  "Beschreibungstext": "Flacher Stein ... [partially correct]"
}
Fine-tuning improved several parts of the prediction:
- The header changed from
Anthropologisch-prähistorifchetoAnthropologisch=prähistorische. - The inventory number changed from
J.-Nr. E024toEo 24, which the authors identify as a correction. - The nested dimensions became
"L": "6,25", "B": "3,95", "D": "1,7", recovering measurements left blank in the zero-shot output.
However, the paper explicitly notes continuing difficulty with longer handwritten text and the separation of Fundort from Fundzeit. The fine-tuned excerpt places "Spy, Belgien Ausbeute Helin" in Fundort and leaves Fundzeit empty. The excerpt does not establish the correct assignment of every phrase or explain its historical meaning.
This example captures the broader challenge: a lower overall error rate and a parsable JSON object can coexist with unresolved field-boundary errors.
Why it matters for document engineering and GLAM pipelines
For software architects, ML engineers, and archival digitization teams, this study offers practical guidance within the scope of its three collections:
- Evaluate instruction-tuned VLMs when you need direct JSON extraction: Gemma-3-4B, Phi-3.5-Vision, and Qwen2.5-VL-7B were the strongest overall candidates for reliable structured generation. That does not establish that specialized OCR engines should be discarded: the benchmark tested particular models and interfaces, and some specialized models performed well after fine-tuning on individual collections.
- Test few-shot prompting instead of assuming it helps: Demonstrations improved all four evaluated models on Jewelry, but results were mixed on handwriting and nested forms. Compare zero-shot and few-shot results on representative documents before choosing a prompting strategy.
- Keep a raw-image baseline when testing cleanup: The complete preprocessing pipeline often reduced structured-extraction scores, but its effect depended on the model, dataset, and metric. These findings support empirical comparison, not a blanket prohibition on denoising or contrast adjustment.
- Consider HPO for complex forms, while tracking multiple metrics: Optuna-selected settings substantially improved Scalalogy results. CER fell from 14.6% to 3.4% for Gemma, 6.3% to 3.2% for Phi, and 7.6% to 3.1% for Qwen. On handwriting, however, lower CER sometimes accompanied worse mAP-F1.
- Audit multi-dataset checkpoints for negative transfer: Evaluate each collection separately before consolidating models. Dataset-specific checkpoints performed substantially better for Phi and Qwen on some collections, while Gemma benefited consistently from joint training.
Honest Limitations and What to Watch Next
The results provide useful evidence, but their scope matters:
- Independent vs. Combined Studies: The authors tested HPO, preprocessing, and multi-stage training independently. Whether combining those interventions produces additional gains remains untested.
- Constrained Decoding Remains Future Work: The evaluations used greedy decoding, reported as temperature 0. The authors propose constrained decoding for valid JSON as a future direction, but do not demonstrate its effect here. Syntactic validity would still need to be distinguished from correct fields and values.
- Compute Parity: Larger models were adapted with QLoRA, while sub-1B models underwent full fine-tuning. Controlled comparisons of those approaches under matched compute budgets remain future work.
- Collection and Model Coverage: The benchmark covers three specialized collections, with test sets of 46, 89, and 25 documents. The authors caution that the model landscape evolves rapidly and call for broader multilingual evaluation, handwriting-specific adaptation, and layout-aware field binding.
- Cloud Replacement Was Not Directly Benchmarked: The experiments do not compare these models against commercial API systems or manual transcription, and do not quantify cost or energy savings. They demonstrate local-model extraction results rather than measured superiority over those alternatives.
The broader takeaway is promising: carefully adapted lightweight VLMs can support institution-controlled OCR-to-JSON extraction on specialized archival records. The reported 4B–7B QLoRA results show substantial gains, especially on printed jewelry cards, while handwriting and nested forms retain meaningful errors. For institutions considering an alternative to commercial APIs, this study supplies candidate models and adaptation strategies—and a clear reason to evaluate content accuracy, field assignment, and JSON validity together.